Ferrum - Run local LLMs with one Rust binary
Ferrum
Run local LLMs with one Rust binary
Screenshots
Hunter's comment
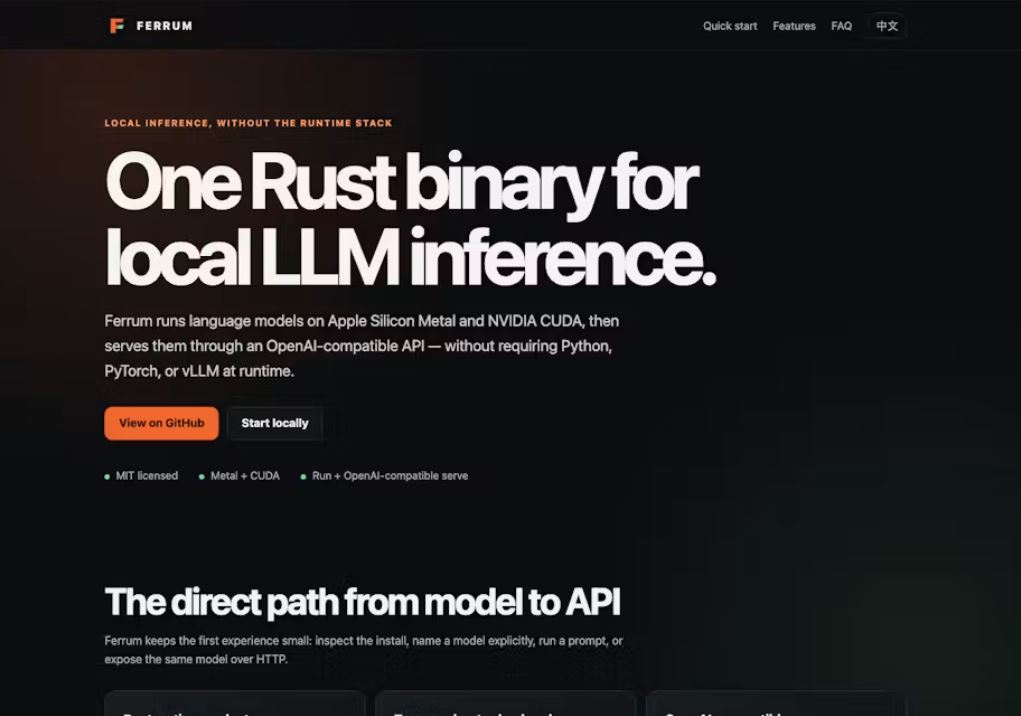
Ferrum is an open-source, Rust-native runtime for running and serving local language models on Apple Silicon Metal and NVIDIA CUDA. One binary gives you an interactive CLI plus OpenAI-compatible Chat Completions and Responses APIs, without requiring Python, PyTorch, or vLLM at runtime. Choose a model explicitly, run it locally, or expose the same model over HTTP.
Link
https://ferrum.pandaailabs.com/

This is posted on Steemhunt - A place where you can dig products and earn STEEM.
View on Steemhunt.com
Congratulations!
We have upvoted your post for your contribution within our community.
Thanks again and look forward to seeing your next hunt!
Want to chat? Join us on: